
A category is a section of your site, and a tag is a detail inside a post. That much is settled, and when I looked at the United States results for this question on 14 August 2026, every page on the first screen said some version of it.
What almost none of them tell you is what WordPress builds behind those two choices, and what those archive pages are doing in Google right now. I pulled my own numbers for this one, and they are small enough that I will show you exactly how small.
Key Takeaways
- Categories are broad, hierarchical and required. Every post gets at least one, and WordPress files anything unassigned under Uncategorized.
- Tags are specific, flat and completely optional. They cross categories, which is the whole point of them.
- WordPress builds a real archive page for every category and every tag you create, plus paginated versions of the big ones.
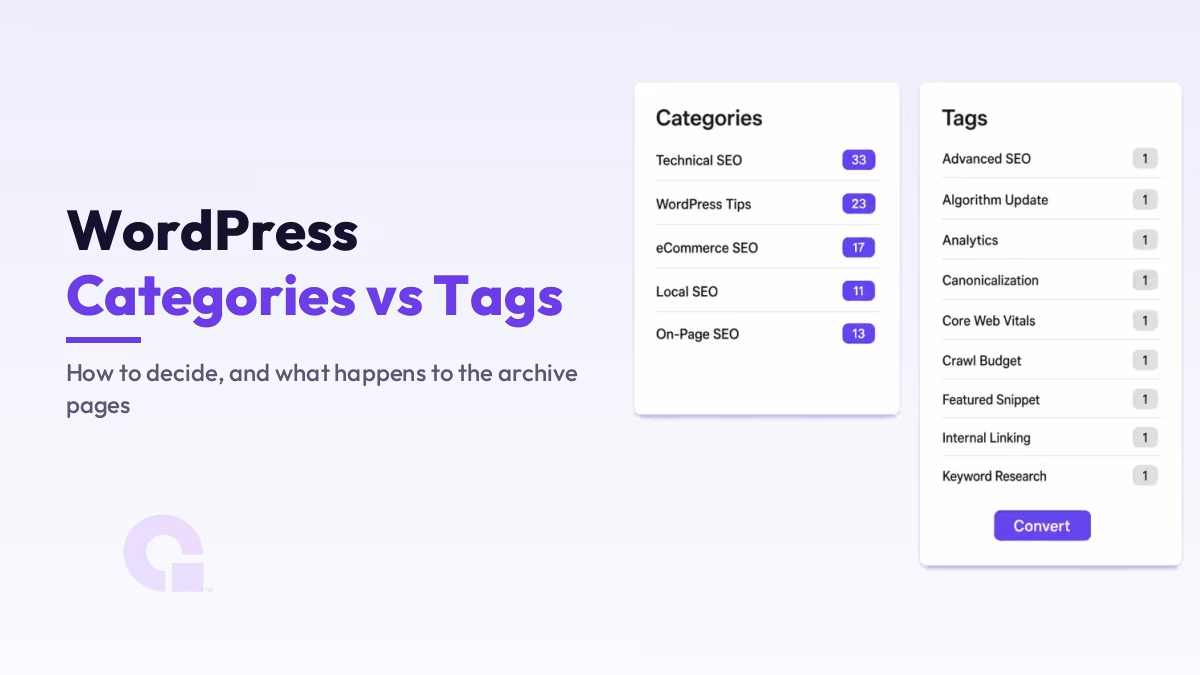
- WordPress ships a tag to category converter and a category to tag converter, both sitting at the bottom of the screens you already use.
- Deleting a category does not delete its posts. Posts that were only in that category move to Uncategorized.
- You cannot use the same name for a category and a tag on the same site.
- The strongest reason to noindex a tag archive is that it holds one post and would embarrass you in a search result. Google’s own documentation says noindex will not save you crawling in the short run, though it can free some up over time.
- Before you switch any archive off, spend two minutes in Search Console finding out whether it is doing anything.
What is the difference between categories and tags in WordPress?
Categories are broad groupings that sit in a hierarchy, and WordPress requires every post to have at least one. Tags are specific keyword-style labels with no hierarchy at all, and they are optional.
WordPress puts it plainly in its own documentation on categories: they “provide a helpful way to group related posts together”, you “must assign at least one”, and “categories can be organized hierarchically”. If you skip the step, a “default category (uncategorized) will be assigned”.
Its page on tags draws the line the other way: tags “are similar to, but more specific than, categories”, and “the use of tags is completely optional”. Think of them as keywords for what a single post actually discusses.
| Categories | Tags | |
|---|---|---|
| Scope | Broad. A section of the site | Specific. A detail inside a post |
| Structure | Hierarchical, with parent and child | Flat, no parents, no children |
| Required? | Yes. Unassigned posts go to Uncategorized | No. Completely optional |
| Typical count | A handful, each holding many posts | Usually many more, often with one post each |
| What it answers | “Where does this post live?” | “What is mentioned in this post?” |
One small rule that catches people out later: you cannot use the same name for a category and a tag on the same site. If “Local SEO” is already a tag, that name is taken.
How do you decide whether something should be a category or a tag?
WordPress builds a listing page, called an archive page, for every category and tag you create. So ask yourself whether you would send a visitor to that listing page as a section of your site. If you would, make it a category; if you would not, make it a tag.
That test works because it forces you to picture the page WordPress is about to build, rather than the label in the sidebar. A category archive is somewhere a reader might land, so it needs enough posts on it to be worth landing on.
Here is how I run it in practice, and each step is doing a different job:
- Write the category list before the posts. Six to ten sections that describe what your site covers, decided once, so you are not inventing a new category every time a post does not quite fit an old one.
- Give every category a description. If you cannot write two honest sentences about what belongs in it, the category is not a real section of your site and you are about to create an archive page with nothing on it.
- Let tags be the things that cross sections. A tool name, a platform, a specific error message. They earn their keep by connecting posts that live in different categories.
- Only add a tag you can imagine using again. A tag applied to exactly one post produces an archive page with one link on it, and it will stay that way unless you have a plan for it.
The step that gets skipped is the description. Counting off my own admin screens, fourteen of my sixteen categories carry a description and none of my fifty tags does, which tells you I was thinking about the category list and not really thinking about the tag list.
What does WordPress actually create when you add a category or a tag?
Every category and every tag gets its own archive page at a real URL, listing the posts assigned to it. Once a term holds more than a page’s worth of posts, WordPress also generates paginated versions of that archive, like /category/best-seo-practices/page/2/.
So the Count column in your admin is telling you two things at once. It counts the posts inside each term, and the length of the list itself counts the archive pages your site now has, each one with its own URL and title.
Those archive titles come from a template in your SEO plugin, which is why so many of them end up looking alike. Mine sets tag archives to %term% Archives %page% %sep% %sitename%, and a set of near-identical titles is a real source of duplicate title tags in WordPress. It is also worth knowing that Google rewrites plenty of those titles anyway, which I went through in the piece on how title links get changed in the SERPs.
Archive pages also sit inside your internal link structure, whether you planned that or not. If you have never looked at where your own links point, the internal linking audit I ran on this site covers how to see it.
One worry worth clearing up before you start deleting anything: deleting a category does not delete your posts. WordPress says so on the screen itself, and posts that were only in the deleted category move to Uncategorized.

How many tags should you use on a WordPress site?
There is no correct number of tags, but there is a test for each one: a tag should hold more than one post, and it should not have a near-twin sitting next to it in the list.
I put it as a test rather than a number because the two things a beginner is most likely to read set very different expectations. Google’s AI Overview for wordpress tags vs categories, which I captured in the United States signed out on 14 August 2026, lists as best practice that “you can create dozens or hundreds of unique tags”.
The page ranking second for that same query on the same capture is WordPress’s own tutorial, and it spends its time warning you off exactly that. Its Categories vs. Tags lesson asks you not to overuse tags, because “it’s better to have a limited number of well utilized tags, rather than hundreds of rarely used ones”, and to “ensure that each category and tag is unique and doesn’t have a synonymous counterpart on your site”.
Read carefully, those two are not strictly in conflict. One says you are allowed to create a large number of tags; the other says a large number of tags nobody uses is a problem. The disagreement is about whether the tags get used, not about how many you may make.
That is exactly why a count is the wrong thing to aim at, and both of them are recommendations rather than measured results anyway. So instead of picking a number, here is my own tag list.

Counted across all three pages of that screen, fifty tag terms exist on this site, forty-eight of them are attached to at least one post, and thirty-eight hold exactly one. Against that, sixteen categories, fifteen of them in use.
It gets worse when you read the names. On this first screen alone, “cluster pages” and “Content Cluster” are the same idea typed twice, and “growing niche series” and “Growing Niches” are another pair. Further down the list, “GSC” and “Google Search Console” are the same tool.
That is what a list of tags you made up as you went actually looks like, and I am showing you mine so you know I am not lecturing from a clean site. Thirty-eight archive pages holding a single link each is the real cost of it.
If your tag archives are indexed, pages that thin are also candidates for the crawled, currently not indexed status in Search Console. Mine are set to noindex and the one I inspected had never been crawled, which I come back to further down, so that is a risk I am pointing at rather than one I have measured here.
How do you convert tags to categories in WordPress?
WordPress ships a built-in converter that turns tags into categories, and it runs the other way too. Go to Posts → Tags and click the tag to category converter link at the bottom of the screen, or Posts → Categories for the category to tag converter.
That link drops you on the Import screen, where Categories and Tags Converter sits in the list of import methods. On my own site the link under it reads Install Now, not Run Importer, because the converter is a small plugin WordPress downloads on demand rather than something already sitting on your install.

So the real sequence is install it, then click Run Importer on the same row once it has installed, then pick the terms you want to move and run it. Guides that jump straight to Run Importer will leave you hunting for a button that is not there yet.
WordPress is direct about what happens next: “your tags will be removed and categories will be assigned to the posts that used to be in those tags”. Going the other way, “your categories will be removed and tags will be assigned to the posts that used to be in those categories”. Your posts are not moved or deleted; only the label on them changes.
This is the part that surprises me about the pages ranking for this question. WordPress.com documents the converter with a click path, so it is not a secret. It is just that almost nobody mentions it in a piece about which one to choose, which leaves readers thinking the only way out is editing posts one at a time.
Two things to know before you run it. You cannot convert a tag into a category that already exists under the same name, because of the shared-name rule, so rename one of them first. And the converter will not merge your near-duplicates for you, so tidy those by hand before you start.
Should you noindex your WordPress tag and category archives?
Noindex is the right setting when you do not want a near-empty archive page appearing in search results for your brand. It is the wrong setting to reach for if your reason is saving Googlebot time, and Google’s own crawling documentation is where that reason falls down.
The advice itself is everywhere. Google’s AI Overview for should i noindex wordpress tag pages, again United States and signed out on 14 August 2026, opens with “Yes, you should generally set WordPress tag pages to noindex” and gives three reasons for it.
I checked each of those three reasons against what Google publishes in its own crawling documentation. One of them holds up and two of them do not.
| The reason given | What Google’s documentation says | Where that leaves it |
|---|---|---|
| Prevent duplicate content, because tag pages repeat text already on your posts | The canonicalization guide (last updated 10 July 2026) says “some duplicate content on a site is normal and it’s not a violation of Google’s spam policies”, and that duplicates “are crawled less frequently in order to reduce the crawling load on sites” | Weak as stated. Repeating your own text is not a policy problem, so there is no penalty to avoid here. An archive taking the search result your post wanted is a separate problem, and I cover it further down |
| Avoid thin content, because many tags hold only one or two posts | Nothing in Google’s documentation argues with this, and WordPress’s own tutorial makes the same point about rarely used tags | This one holds up, and it is the strongest of the three |
| Conserve crawl focus, so bots spend time on your important pages | The crawl budget guide (last updated 22 July 2026) says “don’t use noindex, as Google will still request, but then drop the page when it sees a noindex meta tag or header in the HTTP response, wasting crawling time” | Backwards in the short run, because Google still has to fetch the page in order to read the noindex rule on it |
Google gives the fuller version of that third point on its myths about crawling page (last updated 18 December 2025), where it rates “I can use noindex to control crawl budget” as partly true. I want to quote both halves of that answer rather than the convenient one.
However,
Google Search Central, Myths about crawling and indexingnoindexis there to help you keep things out of the index. If you want to ensure that those pages don’t end up in Google’s index, continue usingnoindexand don’t worry about crawl budget. It’s also important to note that if you remove URLs from Google’s index withnoindexor otherwise, Google’s crawlers can focus on other URLs on your site, which meansnoindexcan indirectly free up some crawl budget for your site in the long run.
So keep using noindex for what Google says it is for, which is keeping a page out of the index. Do not expect it to save you crawling in the days after you switch it on.
And on most sites the crawling question does not arise at all. Google’s crawl budget guide opens by telling you not to read it: “if your site doesn’t have a large number of pages that change rapidly, or if your pages seem to be crawled the same day that they are published, you don’t need to read this guide”.
The smallest site it names in its own “who this guide is for” list is “medium or larger sites (10,000+ unique pages) with very rapidly changing content (daily)”, and Google adds that these figures are “a rough estimate to help you classify your site” rather than exact thresholds. This site has fewer than two hundred posts on it, which is a long way below the smallest size Google wrote that guide for.
Two honest limits on that AI Overview before you take any of it to the bank. It is a generated summary and not a statement of Google’s position, so read it as what a beginner will be shown rather than as policy.
And it was one query, in one market, on one day, from one capture. These summaries change between fetches, so yours may not say the same thing.
One more thing I noticed on that capture. The AI Overview listed nine cited hosts, of which three were visible before clicking Show all, and one of those three was a Moz forum post dated 19 February 2014. I cannot tell you what weight it carried in the answer, only that it was there.
The same AI Overview also says, three lines after “yes, you should generally”, to keep tag archives indexed if you write unique descriptions and introductions for them, or if your layout leans on tag archives as landing pages. So even the source giving you the blanket rule attaches a condition to it, and the next section is how you check whether the condition applies to you.
How do you check whether your own archives are ranking?
Filter the Search Console Pages report to your archive URLs and read the impressions and average position for each one. It takes about two minutes, and it turns the noindex question into something you answer with your own numbers.
Here is the exact sequence, and you can run it right now on your own property:
- Open Google Search Console and choose the property for your site, because the numbers are per property and a domain property and a URL-prefix property will not always show the same set of pages.
- Go to Performance and set the date range to 28 days, which is long enough to catch a low-volume archive and short enough to reflect how the site is configured today.
- Click Add filter, choose Page, and filter for URLs containing
/category/, because that is the string WordPress puts in every category archive URL by default. - Scroll past the chart to the table of tabs underneath it, labeled Queries, Pages, Countries and so on, and click Pages. The filter you set in step 3 narrowed the data; this tab decides how the data is broken down.
- Read three columns for each row. Impressions tells you whether that archive is being shown in search results at all, position tells you how high up it is being shown, and clicks tells you whether anyone chose it.
- Repeat the whole thing with
/tag/, because your tag archives may be configured differently from your categories without you ever having chosen that.
Here is what mine returns, pulled on 14 August 2026.

Five category archives came back. My GEO and AEO archive took 10 impressions at an average position of 3.9, the second page of my best practices archive took 9 at 5.8, and the last three took 2 at 28.5, 1 at 7.0 and 1 at 12.0.
That is 23 impressions across 28 days, an average position of 7.3, and zero clicks on every single row.
Those are tiny numbers and I want to be clear about that. Ten impressions in a month proves nothing on its own, and one site over one window tells you nothing about what archive pages do in general.
What it does tell me is that these pages are not invisible. One of them averages position 3.9 across its ten impressions, and an average that low means it has been appearing high on the page at least some of the time, which is enough for me to want to know what it is appearing for before I switch it off.
The zero in the clicks column is the more useful number for me. These pages get shown and nobody picks them, so on my site they are not earning their place, and that is a stronger argument for tidying up my archives than the fact that a guide told me to.
Now the part I have to be straight about, because it would be easy to read the wrong lesson into it. My /tag/ filter returns no data at all, and that is not a discovery about tags.
My SEO plugin sets tag archives to noindex and leaves them out of the sitemap, so they were never in the running. The empty filter only proves they get no impressions, so I inspected one directly: /tag/seo/, my biggest tag with ten posts on it, comes back as unknown to Google with no record of a crawl.
That is one URL out of fifty and I am not going to claim the other forty-nine are identical, though they carry the same settings. It also shows the limit of the noindex rule I quoted earlier: Google has to fetch a page to read a noindex tag on it, but it never fetched this one, because nothing pointed it there in the first place.
My category archives are set the other way, indexed and included in the sitemap, and Search Console names category-sitemap.xml as how it found the one that ranks best. On my site, then, sitemap inclusion and the robots setting are two separate switches doing two separate jobs, and it is worth checking both rather than assuming one covers the other.
One limit on the method, so you are not confused when you try it. My query-level breakdown comes back empty, because the counts sit under Google’s anonymization threshold, so I can see that my archives get impressions but not what for. If your site has more traffic you will see the actual queries, which is a better view than I have.
When does an archive page compete with its own post?
An archive page competes with its own post when both are eligible for the same query and Google shows the archive instead. That is a different problem from the duplicate content question above, because nothing here breaks a policy; you simply get the weaker page in the result.
I have watched it happen on this site. When I searched for one of my own articles on its exact title, my own category archives and a full-text repost of mine were being shown above the article itself, which I wrote up in the keyword cannibalization audit. That piece has the diagnosis, so I am not going to repeat it here.
What it means for this decision is that an archive page deserves to stay in the index while it is a page you would happily send a reader to. When it starts taking the search result meant for the post underneath it, that is the point to change the setting.
Where do you set index or noindex for a taxonomy archive?
In Rank Math the robots setting for a category or tag archive lives under Rank Math SEO → Titles & Meta, where Categories and Tags each get their own panel with an index or noindex control and a separate switch for including that archive in the sitemap.
Set those two deliberately, because they are separate decisions. On this site categories are set to index and are included in the sitemap, while tags are set to noindex and are excluded from it.
I run Rank Math, so that is the only screen I can show you from my own install. Yoast has equivalent controls in its own taxonomy settings, but I have not checked its current screen myself, so go and look rather than taking my word for the menu path.
Whichever plugin you use, run the Search Console check above before you change anything, so you know what you are switching off.
So, does the categories versus tags decision really matter?
Honestly, the choice you make when you first type the label matters much less than what you do with the pile of tags you end up with. Getting a single label wrong costs you very little, because WordPress ships a converter that moves it in a couple of clicks.
The expensive version is what I have on my own site: thirty-eight archive pages with one link on each, and pairs of tags saying the same thing. On top of that sits the standard advice to noindex all your tag archives, which people apply to the whole lot without opening Search Console first.
If this were your site, I would merge the near-duplicate tags first, convert anything that is genuinely a section into a category, and only then look at the archive numbers in Search Console before touching a robots setting. Do it in that order and you will know what each setting on your site is for.
Common questions about WordPress categories and tags
Can a post have both categories and tags?
Yes, and that is the normal setup. A post must have at least one category, and tags are added on top to describe the specifics that cross other categories.
Do WordPress tags help SEO?
Tags help readers move between related posts, which is a real job. I have not found anything in Google’s search documentation that says tags themselves raise or lower rankings, so treat confident claims in either direction with caution.
What happens to my posts if I delete a tag?
Nothing happens to the posts. Deleting a tag removes the label and its archive page, and the posts stay where they are, in their categories.
Work with WpConsults
Not sure what to do with your own archive pages?
Send me your site and I will tell you which of your categories and tags are doing something in search and which ones are just sitting there.
Update Logs
14 Aug 2026
- First published, with my own tag and category lists, a 28-day Search Console read of the archive pages, and the usual reasons for noindexing tag archives checked against Google’s current crawling documentation.
Want our posts to show up more often on Google?
One step & Google will surface this site in your Top Stories.

יתרון נוסף הוא החיסכון במקום. האסלה התלויה יוצרת אשליה של מרחב גדול יותר, שכן הרצפה נשארת חשופה ורציפה.
בעידן שבו כל מטר רבוע בבית הוא נכס יקר ערך, חדר האמבטיה הפך מזמן מזירת רחצה פונקציונלית למרכז עיצובי ואישי.